Jev benchmarks: what the results actually tell you
Read Jev's independent benchmark evidence, separate classification from agent performance, and use a practical evaluation worksheet before choosing a model.
 Ofox
Jev’s new benchmark evidence makes it worth evaluating for bounded classification and routing decisions. It does not establish that Jev replaces a general LLM, that its confidence number is a correctness guarantee, or that adding it to an agent always saves money. The useful question is narrower: does the decision you need resemble the task that was actually measured?
This guide is for developers deciding whether to put TypeSafe AI’s Jev into a workflow. It separates published findings from our interpretation and gives you an evaluation plan you can fill in before spending on integration. We did not rerun the papers or make live Jev inference calls for this article. For the API’s basic concepts, start with the Jev introduction and setup guide.
Start with the comparison you really need
A support queue classifier, an agent choosing a permitted tool, and a model writing a customer response are different jobs. A model that chooses the correct queue still needs another component to compose a reply. Likewise, selecting a tool name does not prove that its arguments are correct, that the caller is authorized, or that the tool succeeded.
Write your decision as a contract: given these inputs, choose among these outputs, with these consequences when wrong. If the output requires unrestricted prose, a new program, an image, or a video, evaluating Jev alone is the wrong experiment. Evaluate the whole application, including the generative model or deterministic code that performs the remaining work.
| Your decision | Useful measurement | What would be a misleading substitute? |
|---|---|---|
| Send a ticket to billing, technical support or manual review | Per-class errors and routing coverage on your tickets | A general knowledge quiz score |
| Select a permitted tool | Valid choice, correct choice, authorization and execution outcome | Merely receiving parseable JSON |
| Filter retrieved passages | Evidence retained and final answer quality | A product-recommendation ranking result |
| Decide whether to escalate | Errors among accepted cases, fallback quality and total cost | Percentage of expensive calls avoided alone |
These are proposed evaluation criteria, not Jev performance claims. They determine which part of the published evidence is relevant to your application.
What the independent benchmark adds
The September 29 independent preprint evaluates jev-1.13.0 on 37 datasets across 346,009 requests, alongside Qwen3.8-27B and Gemma-4-E4B. It is published research, not our reproduction. Read the paper and released materials.
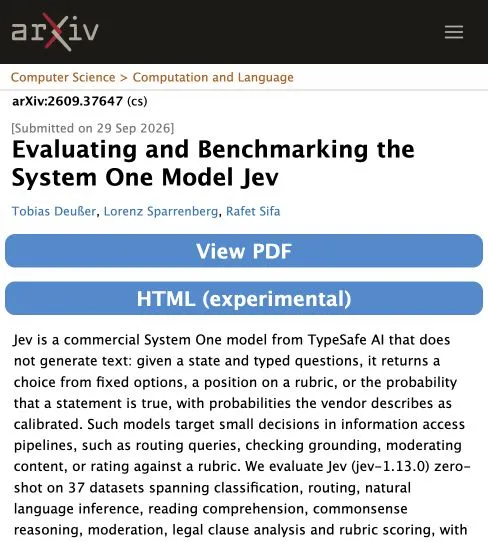
Original English source page captured October 2, 2026. It identifies the research being discussed; it is not a screenshot of an Ofox test.
Treat a published evaluation as a reason to investigate a decision model, rather than approval to deploy it. Your own input population and acceptance rule still determine whether its performance is useful.
Read the authors’ code repository alongside the paper. Before reusing a result, locate the dataset split, request template, question type, model version, metric and uncertainty interval. A table entry detached from those details can answer a different question from the one your system faces.
Read the scores and the weak spots together
The paper reports these results for its fixed requests. Accuracy, balanced accuracy and F1 are different metrics; the rows are not a cross-task ranking.
| Dataset or comparison | Reported result | How to use it |
|---|---|---|
| Banking77, 77-way intent classification | 79.7% accuracy | Test near-neighbor intents before automating your queue |
| CLINC150, including an out-of-scope option | 89.5% accuracy | Include unsupported requests in your own routing set |
| Belebele, 122 languages pooled | 86.7% accuracy | A pooled score cannot approve a particular language |
| LLM-AggreFact | 78.6% balanced accuracy | Evidence for this grounding dataset, not universal truth detection |
| UNFAIR-ToS | Micro-F1 0.499 at a 0.5 yes-probability cutoff; 0.748 with tuned cutoffs | Threshold selection changes a binary decision policy |
| AGB-DE | F1 0.204, unchanged by threshold tuning | Some failures need better discrimination, not a different cutoff |
The UNFAIR-ToS row uses tuned Noul yes-probability cutoffs, not Choice confidence. Qwen and Gemma ran without thinking, on templates written for Jev. Requests ran once. MMLU probes did not exclude memorized question-answer pairs. See Tables 2/4 and the limitations in the preprint.
For an integration decision, those boundaries matter as much as the score. A quick bounded classification experiment and a model allowed to reason through a difficult problem are different products to evaluate. Repeat-run stability, local language performance and high-cost mistakes belong in your acceptance plan even when a headline table omits them. Do not treat an unresolved explanation for a benchmark result as either proof of contamination or proof of reasoning ability.
Why “Jev vs Qwen” is not one universal result
There are at least three reasonable comparisons, and they lead to different buying decisions. First, you can compare models on the same bounded answer set. Second, you can compare the complete cost of an application that produces the same accepted deliverable. Third, you can compare operational constraints, such as hosting, reproducibility and whether your data may leave your environment.
Do not combine a classification score from the first comparison with a chat generation price from the second and call the result a universal winner. A self-hosted baseline also has hardware, utilization and maintenance costs that are not captured by a hosted token price. Conversely, a hosted decision API does not supply every control a local deployment may require.
For a useful comparison table, keep one row per complete task. Record the input population, actual version, allowed outputs, quality rule, retries, latency and total charged cost. If a model does not support the required output, mark that task mismatch explicitly instead of assigning it a low quality score. This avoids pretending that a missing capability is simply weaker performance on a shared capability.
Type-safe output can still mean the wrong decision
A second paper examines what happens when the names of answer options are reassigned to their rubrics. Its hosted Jev results show sensitivity to that change. The lesson is practical: a valid output label does not prove that the model applied your intended meaning. The paper also evaluates other model families, so their larger numerical effects must not be attributed to Jev. See the option-naming study, version 2.
For hosted Jev, reassigning yes/no names to definitions flipped 32.5% of decisions on 1,200 questions; the neutral 0/1 control flipped 2.08%. The much larger 76.92% yes/no flip rate belongs to Laya, not Jev. This is a deliberately conflicting name-definition test, not an estimate that 32.5% of ordinary Jev requests fail. It also differs from merely rotating answer positions in the benchmark above.
Suppose your label approve is attached to a rubric describing cases that require manual review. Your application may faithfully execute the returned label while the question itself is poorly designed. Avoid contradictory names and descriptions, and test the exact mapping your production code will consume. Do not translate labels, reorder rubrics or rename options after evaluation without a regression check.
A useful test set includes ordinary cases, near-boundary cases, incomplete inputs and examples that tempt the model to follow the label name rather than the rubric. Keep synthetic adversarial fixtures separate from naturally occurring traffic. You need both, but an artificial stress set should not silently become your estimate of everyday error frequency.
Agent efficiency needs an end-to-end test
The REFLEX study evaluates a design that uses Jev for bounded decisions and falls back to a stronger model when necessary. It reports efficiency benefits in its controlled setting, but also limited advantages against a cheap generative cascade in external evaluations. That counterexample matters: compare against the economical alternative you would actually deploy, not only an expensive strong-model-only baseline. Read REFLEX.
For your system, count a task as successful only when its final result passes the same acceptance rule across all architectures. A route selected quickly may still produce an incorrect final answer. A fallback can improve reliability but add time, tokens and a second failure opportunity. Tool errors, empty responses and retried requests belong in the denominator rather than disappearing from the report.
The routing cost guide provides a calculator for this comparison. Use observed costs when available; treat illustrative rates as assumptions. The confidence evaluation guide explains how to measure how much traffic a proposed threshold actually accepts.
Build an evaluation your team can reproduce
Download the evaluation worksheet and offline decision kit. The CSV worksheet records the decisions below. It is deliberately separate from a model leaderboard: its purpose is to make your acceptance criteria inspectable.
- Define the eligible population. State which requests enter the experiment. Include the languages, document lengths and ambiguous cases that occur in your application. Excluding difficult traffic changes the claim you can make.
- Write a label guide. Have a person label examples from the source material without seeing the model answer. Resolve disagreements and retain an uncertain category when the evidence genuinely does not permit a decision.
- Split by the unit that can leak. Keep the same customer conversation, document family or near-duplicate template in one split. A random row split can put almost identical cases into tuning and final evaluation.
- Freeze the system. Record the model identifier, question text, labels, fallback rules and preprocessing. A changed question is a changed experiment even when the model name stays the same.
- Evaluate alternatives on matching inputs. Include a rules baseline where feasible, a cheap model cascade, and your current system. All should face the same quality rule and measurement boundary.
- Inspect errors before accepting averages. Break out rare but expensive mistakes. A high overall accuracy can hide a routing class that almost never works.
- Run shadow traffic before automatic action. Log the proposed route while the existing path remains authoritative. Compare results and costs without letting an unvalidated decision trigger consequential side effects.
The output should be a short decision record: what can be automated, what falls back, which cases remain unsupported, and what would trigger rollback. “The average improved” is incomplete without the population and failure boundary.
What to do when your result disagrees with a paper
First check whether you are measuring the same task. Then compare the model version, input representation, option wording, language mix and scoring rule. A published benchmark and a production sample can both be correctly measured while describing different populations.
If accuracy is acceptable but coverage is low, investigate whether your questions combine several judgments or omit important context. If high-confidence errors persist, inspect those examples individually rather than lowering the threshold to improve throughput. If the decision is good but the final task fails, focus on the downstream handler or fallback path.
There is no need to turn a disappointing result into a claim that the model is useless. Keep the narrower conclusion: this version and question design did not meet this task’s acceptance criteria. Equally, one successful routing test does not validate unrelated languages, tools or workloads.
Choosing the next step
Jev is a reasonable candidate when the answer space is bounded and a decision can remove real work from the rest of your pipeline. Use published benchmarks to choose experiments, not to skip them. If your actual task requires generation, evaluate Jev as one component and keep the complete output, cost and failure behavior in view.
Start by filling in the worksheet’s quality rule and fallback policy. Those two decisions make a subsequent threshold test meaningful—and help you avoid buying an impressive benchmark result that solves a different problem.
Frequently Asked Questions
- Does Jev's benchmark prove it can replace an LLM?
- No. The evaluation studies bounded decisions, not general text generation or end-to-end coding. Match the task, interface, baseline and evaluation method before choosing a model.
- Is this an Ofox hands-on Jev benchmark?
- No. This is an analysis of published research and official documentation. The included worksheet is an original evaluation aid, not a new model test.