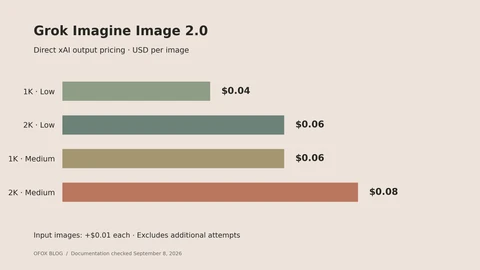
Grok Imagine Image 2.0 API Pricing by Quality
Compare Grok Imagine Image 2.0 API pricing across quality and resolution, calculate editing costs, and budget for 100 or 1,000 generated images with examples.
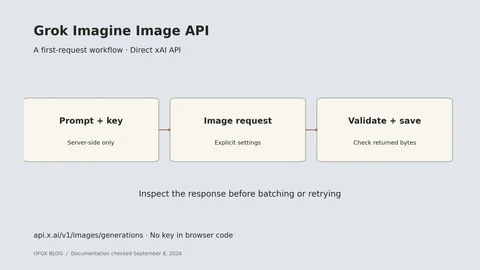
Grok Imagine Image API: Generate Your First Image
Use the Grok Imagine Image API with curl and Python. Set quality and resolution, save the returned image, and check common integration mistakes before scaling.
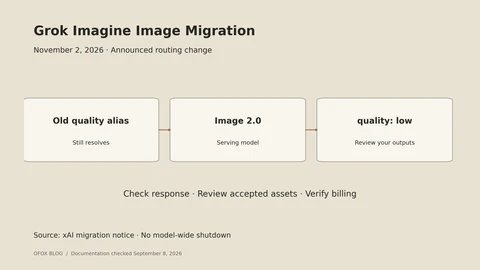
Grok Imagine Image Quality Retirement: What to Change
Prepare for Grok Imagine Image Quality retirement on November 2: check model routing, pin Image 2.0 quality, compare settings, and plan a controlled migration.
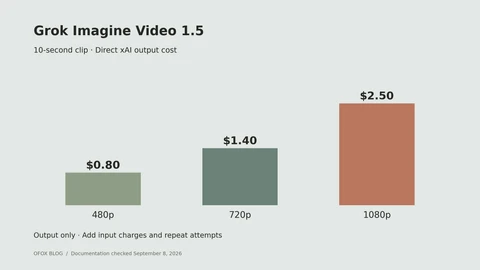
Grok Imagine Video API Pricing by Resolution
Calculate Grok Imagine Video API pricing for 5, 10, and 15 second clips. Compare base and 1.5 rates, input charges, and budgets for repeat generation attempts.
GPT Image 2 Slow? Check Quality, Size and Latency
GPT Image 2 slow? Compare recorded quality-tier timings and output costs, check the default response, and diagnose latency with explicit size and quality.
How Much Does Nano Banana 2 Image Generation Cost?
Check Nano Banana 2 image-token costs, thinking charges and a measured Ofox 512px size mismatch. Learn which response fields to inspect before scaling.
How to Fix ChatGPT DeviceCheck Registration Failed (403, 500, 503)
DeviceCheckError blocks ChatGPT login on iOS, Android and macOS. The date-and-time advice rarely works. What each code means, the browser-cache fix, and the macOS UCRT root cause.
GPT-6 Astra API: Troubleshoot model_not_found, 401 and Token Limits
Real error bodies from the GPT-6 Astra endpoint, plus a measured finding: Astra ignores max_tokens entirely. We asked for 16 and were billed 2,614.
MiniMax H3 API Pricing: Can You Save by Generating Low-Resolution Video First?
MiniMax H3 bills $0.13 per second at 2K and $0.08 at 768P. The 768P-to-2K regeneration tier is $0.05, so $0.08 + $0.05 is exactly $0.13. What that means for real budgets.
Qwen 3.8 Flash API Pricing: Why Can an Empty Answer Still Cost Money?
Qwen 3.8 Flash is the cheapest output rate in the Flash tier at $0.47 per million. It is also a reasoning model, and a short max_tokens returns empty content you still pay for.