Rate Limit Reached in Claude Code: What Each 429 Message Means (2026)
Claude Code shows 'Request rejected (429)' plus the server's own words. Those words tell you who limited you: Anthropic, your gateway, or a free tier.
 Ofox
TL;DR: Claude Code prints API Error: Request rejected (429) · followed by the server’s own message, and that message tells you who limited you (message table). This request would exceed your account's rate limit is Anthropic’s per-minute limit, Server is temporarily limiting requests (not your usage limit) is a server-side throttle, and AI token rate limit exceeded for provider(s) comes from a Kong gateway in front of Claude Code. We reproduced how Claude Code 2.1.304 shows these on 2026-10-20: ten retries over about three minutes, then the message.
You ran a few parallel subagents, or a long agent loop, and Claude Code stops with a red line about a rate limit or “Request rejected (429).” Nothing is broken. In the most common case you hit a per-minute ceiling that your account tier sets, and the API is asking you to wait a specific number of seconds before trying again.
This article is about the API-side 429 you get as a Console / API-key user billed per token. If you are on a Pro or Max subscription and you hit a weekly or session cap instead of a 429, that is a different mechanism with a different fix, covered in Claude Code usage limit hit too fast.
The 30-Second Diagnosis
First thing to settle: which error are you actually looking at, because the fixes diverge hard.
| What you see in the terminal | HTTP status | What it means | First move |
|---|---|---|---|
API Error: Request rejected (429) | 429 | Your account exceeded its own per-minute limit (RPM/ITPM/OTPM) | Read retry-after, then cut concurrency or cache |
API Error: Server is temporarily limiting requests (not your usage limit) | 429 (acceleration limit) | Short-lived throttle after a sharp traffic spike | Wait briefly, ramp traffic gradually |
API Error: Repeated 529 Overloaded errors | 529 | Anthropic’s servers are at capacity for everyone | Wait or /model to a less-loaded model. See the 529 guide |
You've hit your weekly limit · resets Mon | n/a (subscription) | Pro/Max plan allowance, not an API 429 | See the usage-limit guide |
Run this checklist in order:
- Confirm it is a 429, not a 529. Claude Code uses different wording for each. “Request rejected (429)” or “Rate limited” is your account. “529 Overloaded” is the server. Treat them differently.
- Check which credential is active. Run
/status. A strayANTHROPIC_API_KEYin your shell can route you through a low-tier key instead of the account you think you are on. - Look at your tier. Open the Limits page in the Console. Start tier gives Opus 5 and Sonnet 5 1,000 RPM and 2,000,000 ITPM. If your numbers read lower than that, you are in the Evaluation tier, which sits below the published limits while your account builds usage history.
Read the Message After the Dot: Which 429 Do You Have?
Claude Code prints API Error: Request rejected (429) · and then the server’s own message. That second half tells you who limited you, and the fix depends on it.
| Message after the dot | Who limited you | Go to |
|---|---|---|
This request would exceed your account's rate limit. Please try again later. | Anthropic, per-minute limit on your organization | Account rate limit |
Server is temporarily limiting requests (not your usage limit) · Rate limited | Anthropic, server-side throttle | Server throttle |
Usage credits required for 1M context · run /usage-credits… | Claude plan, long-context access | Long context |
AI token rate limit exceeded for provider(s): anthropic | Your organization’s Kong AI Gateway | Gateway budget |
Rate limit exceeded: free-models-per-day… | A routing provider’s free tier | Free tier |
If the message points at a gateway or provider you did not expect, run /status first. A leftover ANTHROPIC_API_KEY or ANTHROPIC_BASE_URL in your shell sends requests through a different key or gateway than the one you think you are using, and its limit is the one you hit.
This Request Would Exceed Your Account’s Rate Limit
API Error: Request rejected (429) · This request would exceed your account's rate limit. Please try again later.This is Anthropic’s per-minute limit on your organization, the case the rest of this guide covers in depth. Claude Code has already waited on retry-after and retried before showing it. If it keeps coming back, lower concurrency, trim context with /compact or /clear, and check your tier on the Limits page. Retry handling for your own scripts is covered in the ofox error handling guide.
Server Is Temporarily Limiting Requests
API Error: Server is temporarily limiting requests (not your usage limit) · Rate limitedThe message itself says this is not your usage limit. In anthropics/claude-code#53915 users report it lasting from minutes to hours while status.claude.com stayed green, and switching models or restarting did not clear it. A sharp jump in your own traffic can also trigger it (the acceleration limit below). Wait, retry later, and avoid starting many sessions at once.
Usage Credits Required for 1M Context
API Error: Usage credits required for 1M context · run /usage-credits to turn them on, or /model to switch to standard contextThe 1M-token context window needs usage credits on your Claude plan. The message lists both fixes: run /usage-credits to turn them on, or /model to switch to a standard-context model. Users in anthropics/claude-code#61869 hit this after selecting a model that defaulted to long context.
AI Token Rate Limit Exceeded for Provider(s)
API Error: Request rejected (429) · AI token rate limit exceeded for provider(s): anthropicThis is not Anthropic’s wording. It is the default error_message of Kong AI Gateway’s AI Rate Limiting Advanced plugin, so your organization sends Claude Code traffic through a Kong gateway that enforces its own token budget. Changing your Anthropic tier will not help. Ask the team that runs the gateway to raise or reset the budget for your consumer.
Rate Limit Exceeded: Free-Models-Per-Day
API Error: Request rejected (429) · Rate limit exceeded: free-models-per-day. Add 10 credits to unlock 1000 free model requests per dayThis comes from a routing provider’s free tier, not Anthropic. The daily free quota is used up, and the message names the provider’s own fix. Use a paid model or key on that provider, or point Claude Code at a different provider. If you route Claude Code through ofox, setup is in the ofox docs for Claude Code.
When to Fix the 429 (and When to Just Wait)
Decide before you start refactoring, because some 429s clear themselves and some need real changes.
When to just retry and wait. If you see an occasional 429 during a burst and retry-after is small (a few seconds), do nothing structural. Claude Code already retries transient 429 and 529 capacity errors up to 10 times with exponential backoff before it surfaces the error, showing a Retrying in Ns · attempt x/y countdown. If the error rate is under roughly 5% of requests, retry is the whole fix.
When to actually change something. If 429s are constant, if they kill subagents mid-task, or if retry-after keeps climbing, you are structurally over your tier’s per-minute budget. Lower concurrency, add caching, or raise your tier. Throwing more retries at a saturated limit just queues more failures.
Stop rule. If you are in the Evaluation tier running parallel subagents over a large repo, no amount of backoff will hold. Either wait for the tier to advance or pool capacity across a gateway. Backoff smooths spikes; it does not raise a ceiling.
What “Rate Limit Reached” and HTTP 429 Actually Mean
A 429 is the HTTP status the Claude API returns when your organization exceeds one of its per-minute rate limits. It is an account-level signal, scoped to your organization, and it is enforced separately for each model. The error body is a rate_limit_error and the message names which limit you hit, for example “This request would exceed your organization’s rate limit of x0,000 input tokens per minute.” The API also attaches a retry-after header.
There are three per-minute dimensions the Messages API enforces, per Anthropic’s rate-limits docs:
- RPM (requests per minute): how many API calls you can make.
- ITPM (input tokens per minute): how many input tokens you can send. This is the one that bites agent workloads, because every turn ships the full conversation context as input.
- OTPM (output tokens per minute): how many tokens the models can generate for you per minute. Note:
max_tokensdoes not factor into OTPM; only the tokens actually produced count, so setting a highmax_tokenshas no rate-limit downside.
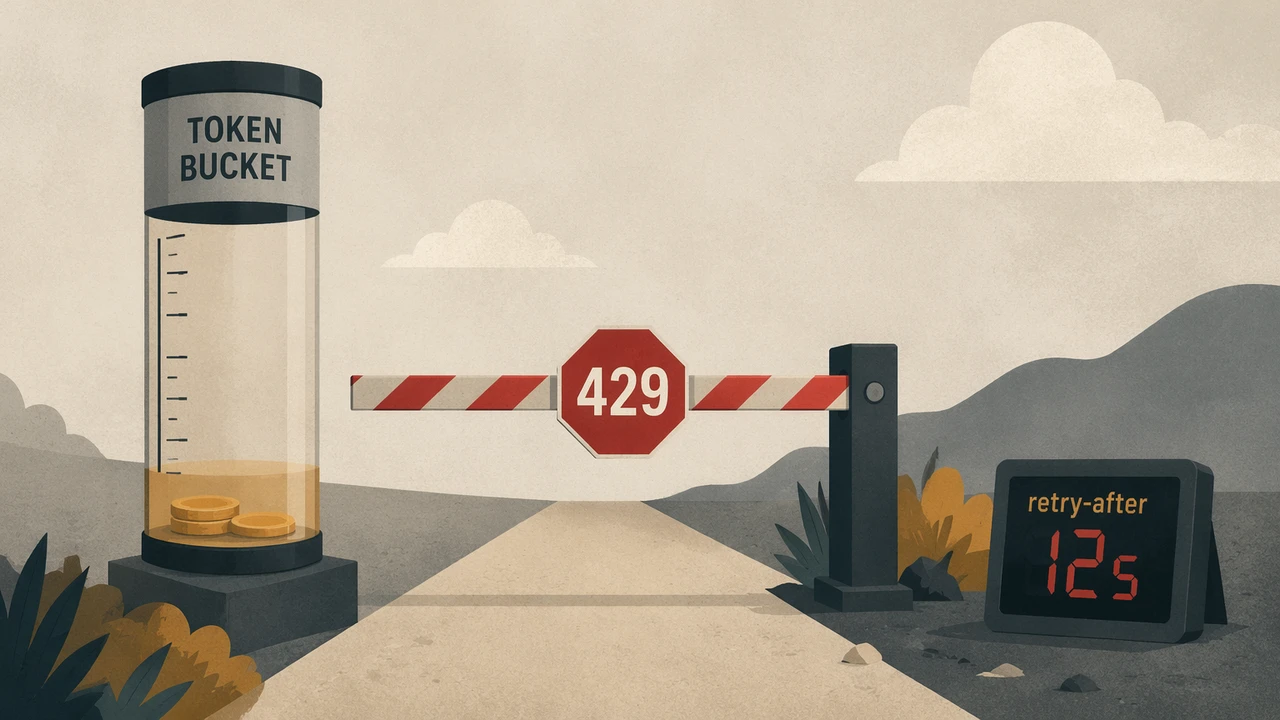
You get a 429 the instant you cross any one of the three. The limit uses a token-bucket algorithm, so your capacity refills continuously rather than resetting at the top of each minute. That also means short bursts can trip the limit even when your minute-averaged usage looks fine: 60 RPM is enforced closer to 1 request per second, not 60 requests fired at once.
Three numbers govern every 429: requests, input tokens, and output tokens per minute. Find which one you are blowing, and the fix picks itself.
The 429 response and the headers that tell you everything
When you hit the limit, the response carries headers that tell you the limit, your remaining budget, and when it refills. These are worth surfacing in any agent loop you build:
HTTP/1.1 429 Too Many Requests
retry-after: 12
anthropic-ratelimit-input-tokens-limit: 30000
anthropic-ratelimit-input-tokens-remaining: 0
anthropic-ratelimit-input-tokens-reset: 2026-06-24T18:42:30Z
retry-after is the number of seconds to wait before retrying; earlier retries will fail. The anthropic-ratelimit-*-limit, -remaining, and -reset headers exist for requests, input tokens, and output tokens separately, so you can watch headroom on each dimension and back off before you trip rather than after.
One caveat the field has learned the hard way: retry-after is a server hint, and on the rolling-window boundary it can read a touch short. Honor it as a floor, then add positive jitter on top so a fleet of workers does not all wake up and retry in the same millisecond.
Error and Symptom to Cause to Fix
| Symptom | Likely cause | Fix |
|---|---|---|
| 429 within seconds of spawning subagents | Concurrency fans out RPM and ITPM at once | Lower CLAUDE_CODE_MAX_TOOL_USE_CONCURRENCY; spawn fewer subagents |
| 429 on a single large turn, no parallelism | One turn’s context exceeds ITPM (Evaluation tier sits below the published caps) | Trim context with /compact or /clear; enable prompt caching |
| 429 right after a quiet period, then a spike | Acceleration limit on sharp usage increase | Ramp traffic gradually; keep a steady request rate |
| 429s appear, dashboard shows quota left | Looking at spend limit, not the per-minute rate limit | Per-minute caps and monthly spend caps are different; check the rate-limit chart |
retry-after keeps growing across retries | You are structurally over the limit, retries pile up | Stop retrying harder; raise tier or pool capacity |
| 429 in CI that should be on a high tier | Stray ANTHROPIC_API_KEY routing to a low-tier key | Run /status; unset the wrong key |
Why It Trips: Concurrency, Token Bursts, and No Backoff
Three patterns cause almost every Claude Code 429.
Parallel subagents and parallel sessions. This is the big one. When Claude Code fans out subagents through the Task tool, each subagent is a separate stream of requests, and each one carries its own copy of the context as input tokens. Run six subagents over a large repository and your ITPM and RPM both spike at once. A known Claude Code issue documents 5-10 parallel sessions launching subagent fan-outs and hard-failing under capacity errors. Reduce the fan-out and the 429s stop.
Context bursts on a tight tier. Evaluation-tier organizations run below the published Start numbers, and the Console is the only place the real figure is shown. If your ITPM cap is a few tens of thousands and your conversation context has grown to 25,000 tokens, one new message consumes most of your per-minute input budget, and a second message in the same minute trips the 429. This is “prompt bloat”: the session got larger than the task needs. Run /context to see what is filling the window, then /compact or /clear.
No backoff in your own scripts. Claude Code itself retries with exponential backoff. But if you are hitting the API directly around Claude Code (a CI wrapper, a custom agent loop), and you retry on a fixed interval with no jitter, every worker retries in lockstep and re-trips the limit together. Synchronized retries are how a brief throttle becomes a sustained outage.
How to Fix It: Solutions for Every Tier
Evaluation tier: read the header, cut the burst
If you are on the lowest tier, you have the least headroom, so behave accordingly.
- Honor
retry-after. Wait the number of seconds the header says, then add jitter. Do not retry early. - Shrink context. Run
/compactat natural breakpoints or/clearto start fresh. Less context per turn means less ITPM per request. - Drop concurrency to near-serial. Set the concurrency cap low so you are not fanning out requests you cannot afford.
# Lower tool-use concurrency before a heavy session
export CLAUDE_CODE_MAX_TOOL_USE_CONCURRENCY=2
# Surface failures faster in scripts instead of retrying 10x
export CLAUDE_CODE_MAX_RETRIES=3
claude
Start and Build tiers: caching and exponential backoff
Once you have some headroom, the leverage is caching plus disciplined retries.
Prompt caching cuts ITPM, not just cost. On most current Claude models, cache_read_input_tokens do not count toward your ITPM limit. Anthropic’s own example: with a 2,000,000 ITPM limit and an 80% cache hit rate, you can effectively process about 10,000,000 total input tokens per minute, because the cached 8M is free against the rate limit. Cache your system prompt, tool definitions, and large context documents. For the mechanics of trimming token usage end to end, see Claude Code token optimization.
Exponential backoff with jitter is the correct retry shape when you control the loop:
import random, time

def backoff_sleep(attempt, retry_after=None):
    if retry_after is not None:        # honor the server hint as a floor
        base = float(retry_after)
    else:
        base = min(2 ** attempt, 60)   # 1, 2, 4, 8 ... capped at 60s
    time.sleep(base + random.uniform(0, base * 0.25))  # add jitter
For unattended runs like CI, you can also set CLAUDE_CODE_RETRY_WATCHDOG=1 so Claude Code retries 429 and 529 capacity errors indefinitely instead of giving up after CLAUDE_CODE_MAX_RETRIES attempts.
Scale and Custom tiers: raise the ceiling or pool it
When backoff and caching are not enough, you need more limit.
- Advance your tier. Placement is automatic, based on usage history and account standing. Scale gives Opus 5 and Sonnet 5 10,000 RPM and 10,000,000 ITPM, five times the Start figures. To move sooner, use Request rate limit increase on the Rate limits page in the Console; above Scale, the Custom tier is arranged with your account team.
- Set per-workspace caps so one project cannot starve the rest of the organization. Workspace limits carve up the org’s per-minute budget per limiter type.
- Spread load across providers or pool capacity. If your workload is bursty and a single organization’s per-minute caps are the bottleneck, a routing layer in front of multiple providers widens the effective ceiling. More on the pattern in the Claude Code hybrid routing guide.
Anthropic rate limits by tier
The numbered tiers are gone. Anthropic now names them Evaluation, Start, Build, Scale and Custom, and placement is automatic based on usage history and account standing rather than a cumulative credit threshold. If you are reading a guide that says “Tier 1 gets 50 RPM,” it predates the change. The current per-minute caps, from the official rate-limits docs:
| Model | Start RPM / ITPM / OTPM | Build | Scale |
|---|---|---|---|
| Opus 5, Opus 4.x, Sonnet 5, Sonnet 4.x, Haiku 4.5 | 1,000 / 2,000,000 / 400,000 | 5,000 / 5,000,000 / 1,000,000 | 10,000 / 10,000,000 / 2,000,000 |
| Fable 5 | 1,000 / 500,000 / 100,000 | 2,000 / 1,500,000 / 300,000 | 4,000 / 4,000,000 / 800,000 |
| Haiku 3.5 (retired outside Bedrock and Google Cloud) | 1,000 / 100,000 / 20,000 | 2,000 / 200,000 / 40,000 | 4,000 / 400,000 / 80,000 |
Four things the table does not say out loud:
- Evaluation is not in it. New organizations and organizations with limited history start below these numbers and rise automatically. The Console is the only place your actual figure is shown.
- Version families share one bucket. The Opus 4.x row is a single total across Opus 4.8, 4.7, 4.6 and 4.5; Sonnet 4.x is shared across 4.6 and 4.5. Switching versions inside a family does not give you a fresh bucket. Opus 5 and Sonnet 5 each have their own, separate from the 4.x pools, so moving a job from Opus 4.8 to Opus 5 genuinely does move it off a contended bucket.
- Different models run in parallel. Limits apply per model, so an Opus job and a Sonnet job draw from their own pools at the same time. Routing cheap, high-volume work to Haiku 4.5 keeps it off both.
- Cache reads are free against ITPM. On every model above except Haiku 3.5,
cache_read_input_tokensdo not count toward the input limit. Onlyinput_tokensandcache_creation_input_tokensdo. At an 80% hit rate against a 2,000,000 ITPM cap, that is roughly 10,000,000 total input tokens per minute of real throughput.
The acceleration limit: the 429 that has nothing to do with your tier
There is a second flavor of 429 worth knowing about, because it surprises people who are nowhere near their tier ceiling. If your organization’s usage jumps sharply, the API can apply an acceleration limit and return a 429 even though your per-minute caps have headroom. The intent is to stop runaway spikes, not to punish steady use. The fix is not “raise my tier,” it is “ramp up gradually.” Warm a new workload in over a minute or two instead of firing peak traffic from a cold start, and keep your request rate roughly consistent. In Claude Code this is the throttle behind the Server is temporarily limiting requests (not your usage limit) message, which the CLI already retries for you before surfacing it.
Spread the load instead of stacking it
Most agent 429s come from doing everything in one tight window. A few cheap scheduling habits make the same total work fit under the same caps:
- Serialize the expensive turns. A single large-context turn can be most of your ITPM minute in the Evaluation tier. Run those one at a time rather than letting subagents fire them in parallel.
- Batch the non-urgent work. If a job does not need a live answer, the Message Batches API has its own separate limits, so moving bulk work there frees your interactive RPM and token budgets.
- Stagger CI jobs. Do not schedule ten pipelines to start on the same cron minute. Offset their start times so their first bursts do not collide on the same bucket.
Rate Limit or Spend Cap? The Two 429s That Look Identical
Both return HTTP 429 with "type": "rate_limit_error", and only one of them is worth retrying. This is the single most expensive confusion in the 429 family, because a retry loop pointed at the wrong one will burn the rest of your month against a wall.
A per-minute rate limit clears in seconds. A monthly spend cap does not clear until 00:00 UTC on the first of the next month. Anthropic ships two discriminators:
- The
retry-afterheader. A real rate limit carries one. The spend-cap 429 does not send it at all. If your handler keys offretry-after, an absent header is your signal to stop, not to guess a delay. error.details.error_code. On the Messages API the spend-cap response carriesenforced_spend_limit_reached. The message spells out the resume date: “You will regain access on 2026-09-01 at 00:00 UTC.”
There is a third variant that is not a 429 at all. A spend limit you set below your tier’s cap returns HTTP 400 with invalid_request_error, and the message begins “You have reached your specified API usage limits.” Raising or removing your own limit restores access immediately; nothing else will.
The caps themselves, per Anthropic’s rate-limits docs:
| Usage tier | Monthly spend cap |
|---|---|
| Start | $500 |
| Build | $1,000 |
| Scale | $200,000 |
| Custom | No cap; arranged with your account team |
The Claude Code workspace is checked separately, and requests over that workspace’s limit can come back as a 429 with a retry-after header, so a Claude Code session can be throttled by a workspace ceiling while the rest of your organization is fine.
Backoff and jitter, concretely
retry-after is a floor, not a schedule. Honor it, then add positive jitter so a fleet of workers does not wake up together and re-trip the same bucket:
import random, time

def wait_for(resp, attempt):
    # Spend cap: no retry-after, no point retrying.
    if resp.status_code == 429 and "retry-after" not in resp.headers:
        raise RuntimeError("spend cap reached; retrying will not help")
    floor = float(resp.headers.get("retry-after", 0))
    backoff = min(2 ** attempt, 60)          # exponential, capped
    time.sleep(max(floor, backoff) + random.uniform(0, 1))   # full jitter on top
Three properties matter and all three are easy to get wrong: the floor comes from the server rather than your own guess, the exponential term is capped so a long outage does not push you into hour-long sleeps, and the jitter is added after the max rather than baked into it, so it can never take you below retry-after.
Common Failure Patterns We’ve Observed in 2026
Recurring shapes the field keeps reporting, drawn from the Claude Code issue tracker and support threads:
| Pattern | Trigger | What fixes it |
|---|---|---|
| Subagent fan-out hard-fail | 6+ parallel subagents on large context | Lower concurrency cap; reduce fan-out |
| 529 mislabeled as “Rate limited” | Server overload during parallel sessions | Recognize it is 529, not your quota; wait or /model switch |
| 429 despite “available quota” on dashboard | Confusing monthly spend limit with per-minute rate limit | Read the rate-limit chart, not the spend chart |
/batch-style burst rejected (429) | Many requests fired in one tight window | Stagger requests; respect the token bucket |
| CI loops re-tripping the same limit | Fixed-interval retries with no jitter | Exponential backoff plus random jitter |
These are mechanism patterns, not a published incident log. The throughline is the same: find the dimension you are saturating, then either slow it down or widen it.
When You Need More Headroom: Best Alternatives That Work Now
If your bottleneck is one organization’s per-minute caps, here are the realistic options. Which one fits depends on whether you are hitting a request limit or a token limit.
Route Claude Code through ofox. ofox accepts Claude Code’s Anthropic-format requests at https://api.ofox.ai/anthropic (setup guide). Its documented default is 100 requests per minute, shared across all API keys in your team, with no tokens-per-minute limit (ofox rate limits); the request limit can be raised by contacting hi@ofox.ai. With the default, it suits long-context sessions that trip an input-token limit. For request-heavy fan-out, such as many parallel subagents, ask for a higher limit before switching: the default 100 is below Anthropic’s Start tier of 1,000.
export ANTHROPIC_BASE_URL=https://api.ofox.ai/anthropic
export ANTHROPIC_AUTH_TOKEN=YOUR_OFOX_KEY
claude
Use the model IDs listed on the ofox models page, for example anthropic/claude-opus-4.8. Billing is pay-as-you-go at each model’s listed price.
Raise your Anthropic tier. The cleanest fix if you want to stay single-provider. Placement is automatic based on usage history, so to move sooner use Request rate limit increase on the Rate limits page in the Console. Best when your traffic is predictable and you can commit spend.
Multi-provider routing on your side. Run your own router that spreads requests across providers and respects each one’s retry-after. Most control, most code to maintain. The hybrid routing pattern covers the design.
How to Monitor Rate Limits and Get Ahead of 429s
You can see a 429 coming before it lands. Three places to watch:
- The Console Usage page has two rate-limit charts: hourly maximum uncached input tokens per minute against your current ITPM cap, and the same for output tokens. It also shows your cache hit rate, which tells you how much ITPM headroom caching is buying you.
- The response headers (
anthropic-ratelimit-*-remainingand-reset) let your own code throttle proactively. When remaining input tokens approach zero, slow down before the bucket empties. - Anthropic status at status.claude.com tells you whether a wave of “rate limited” messages is actually a 529 capacity event affecting everyone, in which case the fix is patience, not config.
For the same status code at other providers, LLM API error codes lays five of them out side by side.
Test Results: How Claude Code Shows a 429
Claude Code 2.1.304, 2026-10-20, macOS, ANTHROPIC_BASE_URL pointed at a local server that returns HTTP 429 with retry-after: 1 and the body below.
| Body returned | Requests before giving up | Time | What Claude Code printed |
|---|---|---|---|
Anthropic rate_limit_error, “This request would exceed your account’s rate limit…“ | 11 | 207 s | API Error: Request rejected (429) · This request would exceed your account's rate limit. Please try again later. |
| Kong default, “AI token rate limit exceeded for provider(s): anthropic” | 11 | 183 s | API Error: Request rejected (429) · AI token rate limit exceeded for provider(s): anthropic |
| Free-tier style, “Rate limit exceeded: free-models-per-day…“ | 11 | 181 s | API Error: Request rejected (429) · Rate limit exceeded: free-models-per-day… |
Not reproduced: Server is temporarily limiting requests and Usage credits required for 1M context. Those sections are based on the linked issues and on Anthropic’s documentation, checked on 2026-10-20.
FAQ
What does API Error: Rate Limit Reached mean in Claude Code?
It means the Claude API returned HTTP 429: your organization sent more requests or tokens per minute than your usage tier allows. It is an account-side throttle on RPM, ITPM, or OTPM, not a server outage. The response carries a retry-after header telling you how many seconds to wait.
Is a 429 the same as a 529 in Claude Code?
No. A 429 (rate_limit_error) means your account exceeded its own per-minute limits. A 529 (overloaded_error) means Anthropic’s servers are temporarily at capacity for everyone, independent of your usage. Claude Code shows them as different messages: “Request rejected (429)” versus “Repeated 529 Overloaded errors.”
How long should I wait after a 429 rate limit error?
Read the retry-after header. It gives the exact number of seconds until you can retry; retrying earlier will fail again. If the header is missing, fall back to exponential backoff starting around 1-2 seconds and doubling, with random jitter so parallel workers do not all retry at the same instant.
Why does Claude Code hit the rate limit so fast with subagents?
Parallel subagents fan out many concurrent requests, and each one carries the full conversation context as input tokens. A handful of subagents on a large context can blow past your ITPM cap in seconds. Lower CLAUDE_CODE_MAX_TOOL_USE_CONCURRENCY or reduce how many subagents you spawn at once.
What are RPM, ITPM, and OTPM in the Anthropic rate limits? RPM is requests per minute, ITPM is input tokens per minute, and OTPM is output tokens per minute. The Messages API enforces all three per model class. You get a 429 the moment you exceed any one of them, and the error names which limit you hit.
How do I raise my Claude API rate limit? Anthropic replaced the numbered Tier 1-4 scheme with named tiers: Evaluation, Start, Build, Scale and Custom. Placement is automatic, based on usage history and account standing rather than a credit threshold you can buy past. To ask for more, use Request rate limit increase on the Rate limits page in the Console. Above Scale, the Custom tier is arranged with your account team.
Does prompt caching help with 429 rate limit errors?
Yes. On most current Claude models, cache_read_input_tokens do not count toward your ITPM limit. With an 80% cache hit rate against a 2,000,000 ITPM cap you can effectively process about 10,000,000 total input tokens per minute, because the cached portion is free against the rate limit.
Can I avoid Claude Code rate limits by switching providers?
Switching changes whose limits apply, not whether limits exist. Through ofox, Claude Code connects to https://api.ofox.ai/anthropic; ofox’s default is 100 requests per minute shared across your team, with no tokens-per-minute limit, and the request limit can be raised by contacting hi@ofox.ai. That helps sessions that hit an input-token limit; for request-heavy workloads, ask for a higher limit first.
What does ‘Server is temporarily limiting requests (not your usage limit)’ mean? The throttle is on the server side, not your plan’s usage. Users in anthropics/claude-code#53915 report it lasting from minutes to hours while the status page stayed green. Wait and retry later; switching models or restarting did not help in that thread.
Where does ‘AI token rate limit exceeded for provider(s): anthropic’ come from? It is the default error message of Kong AI Gateway’s AI Rate Limiting Advanced plugin, not an Anthropic message. Your organization routes Claude Code through a Kong gateway with a token budget; ask whoever runs that gateway to raise or reset it.
Should I keep retrying a 429?
Only if the response has a retry-after header. Anthropic’s monthly spend-cap 429 has no retry-after and does not clear until access resumes, so retries fail until then.
A 429 is the API setting a pace, not slamming a door. Read
retry-after, slow the dimension you are saturating, and the work keeps moving.
Related Docs
- Configure ofox as a Claude Code model provider
- Error handling and retries
- Claude Code in the ofox docs
References
Frequently Asked Questions
- What does API Error: Rate Limit Reached mean in Claude Code?
- It means the Claude API returned HTTP 429: your organization sent more requests or tokens per minute than your usage tier allows. It is an account-side throttle on RPM, ITPM, or OTPM, not a server outage. The response carries a retry-after header telling you how many seconds to wait.
- Is a 429 the same as a 529 in Claude Code?
- No. A 429 (rate_limit_error) means your account exceeded its own per-minute limits. A 529 (overloaded_error) means Anthropic's servers are temporarily at capacity for everyone, independent of your usage. Claude Code shows them as different messages: Request rejected (429) versus Repeated 529 Overloaded errors.
- How long should I wait after a 429 rate limit error?
- Read the retry-after response header. It gives the exact number of seconds until you can retry; retrying earlier will fail again. If the header is missing, fall back to exponential backoff starting around 1-2 seconds and doubling, with random jitter so parallel workers do not all retry at the same instant.
- Why does Claude Code hit the rate limit so fast with subagents?
- Parallel subagents fan out many concurrent requests, and each one carries the full conversation context as input tokens. A handful of subagents on a large context can blow past your ITPM (input tokens per minute) cap in seconds. Lower CLAUDE_CODE_MAX_TOOL_USE_CONCURRENCY or reduce how many subagents you spawn at once.
- What are RPM, ITPM, and OTPM in the Anthropic rate limits?
- RPM is requests per minute, ITPM is input tokens per minute, and OTPM is output tokens per minute. The Messages API enforces all three per model class. You get a 429 the moment you exceed any one of them, and the error names which limit you hit.
- How do I raise my Claude API rate limit?
- Anthropic replaced the numbered Tier 1-4 scheme with named tiers: Evaluation, Start, Build, Scale and Custom. Placement is automatic, based on usage history and account standing rather than a fixed credit threshold you can buy past. To ask for more, use Request rate limit increase on the Rate limits page in the Claude Console. New organizations may start in Evaluation, below the published Start numbers, and move up automatically as usage history builds.
- Does prompt caching help with 429 rate limit errors?
- Yes. On most current Claude models, cache_read_input_tokens do not count toward your ITPM limit. With an 80% cache hit rate against a 2,000,000 ITPM cap you can effectively process about 10,000,000 total input tokens per minute, because the cached portion is free against the rate limit.
- Can I avoid Claude Code rate limits by switching providers?
- Switching changes whose limits apply, not whether limits exist. Through ofox, Claude Code connects to https://api.ofox.ai/anthropic; ofox's default is 100 requests per minute shared across your team, with no tokens-per-minute limit, and the request limit can be raised by contacting hi@ofox.ai. That helps sessions that hit an input-token limit; for request-heavy workloads, ask for a higher limit first.
- What does 'Server is temporarily limiting requests (not your usage limit)' mean?
- The throttle is on the server side, not your plan's usage. Users in anthropics/claude-code#53915 report it lasting from minutes to hours while the status page stayed green. Wait and retry later; switching models or restarting did not help in that thread.
- Where does 'AI token rate limit exceeded for provider(s): anthropic' come from?
- It is the default error message of Kong AI Gateway's AI Rate Limiting Advanced plugin, not an Anthropic message. Your organization routes Claude Code through a Kong gateway with a token budget; ask whoever runs that gateway to raise or reset it.
- Should I keep retrying a 429?
- Only if the response has a retry-after header. Anthropic's monthly spend-cap 429 has no retry-after and does not clear until access resumes, so retries fail until then.